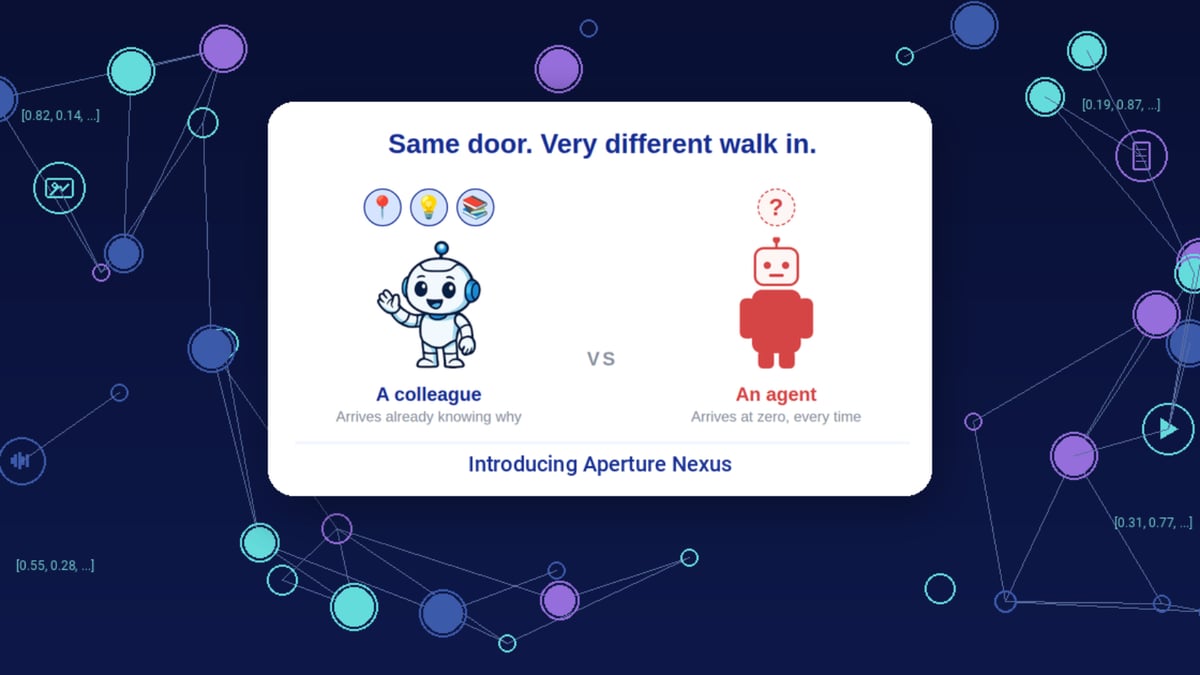
Same Door. Very Different Walk In.
# AI Agents
# Cognition
# Knowledge Graph and Graph Databases
# Multimodal / Generative AI
# Vector / Similarity / Semantic Search
# RAG
An open source memory and cognition layer for AI agents, built on ApertureDB.
September 15, 2026
Vishakha Gupta
Introducing Aperture Nexus: An Open Source Memory and Cognition Layer for AI Agents
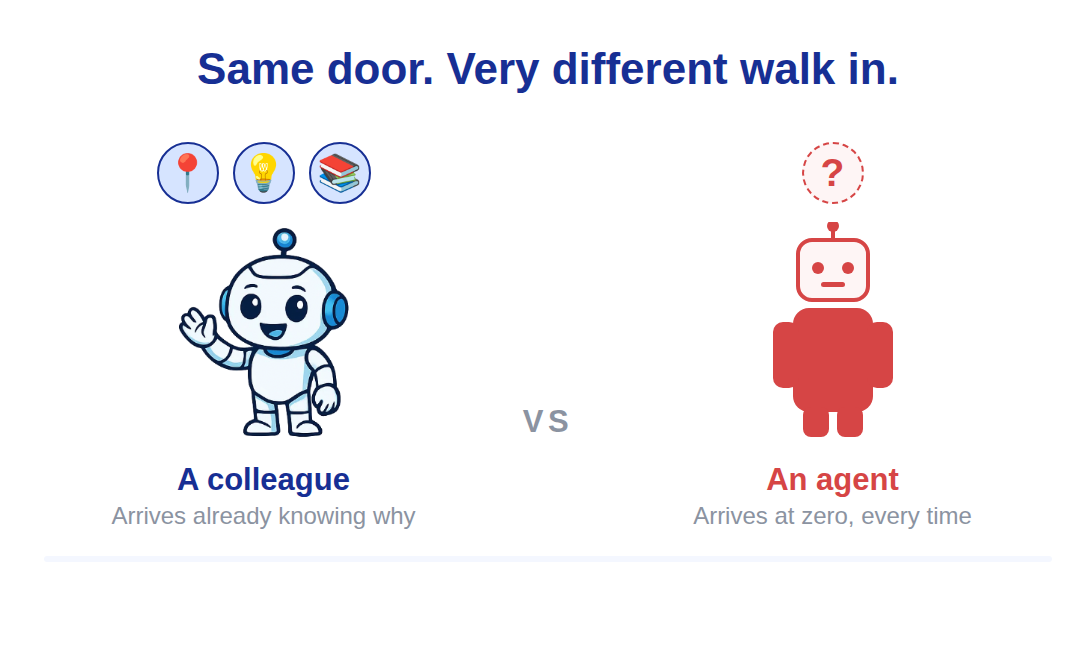
A colleague walks into a new problem already knowing why it matters. An agent walks in at zero, every time.
That gap is not limited to coding agents. It shows up in every AI tool we use. I use Claudette for code and content, Copilot for email and code review, and Gemini for research and podcast. These are different tools with genuinely different strengths, but none of them know what the others know. My own coding or writing preferences live in a file that one tool has read and another has never seen. I rebuild myself from scratch for every tool, sometimes in every session.
The same gap appears at enterprise scale, with more at stake. A customer spends twenty minutes in a support chat explaining that they have switched to a plant-based diet, or that they are planning a wedding, or that the budget is tight this quarter. That is genuinely useful information, but it rarely leaves the support system. Marketing sends the same generic promotion two days later, the exact offer the customer already said they did not want. No one made a mistake. The two systems simply never shared what either of them had learned.
People notice this. It is why "this company does not know me" is such a common complaint, not because no one on the other end actually knew, but because knowing something in one system and acting on it in another turns out to be the hard part.
If that sounds familiar, this piece is about the problem you have felt. It is not unique to engineers, or to any single AI product. It is what happens when intelligence has no persistent sense of who it is talking to, what has already been decided, or why any of it matters.
What We Learned Auditing 20+ Memory Frameworks
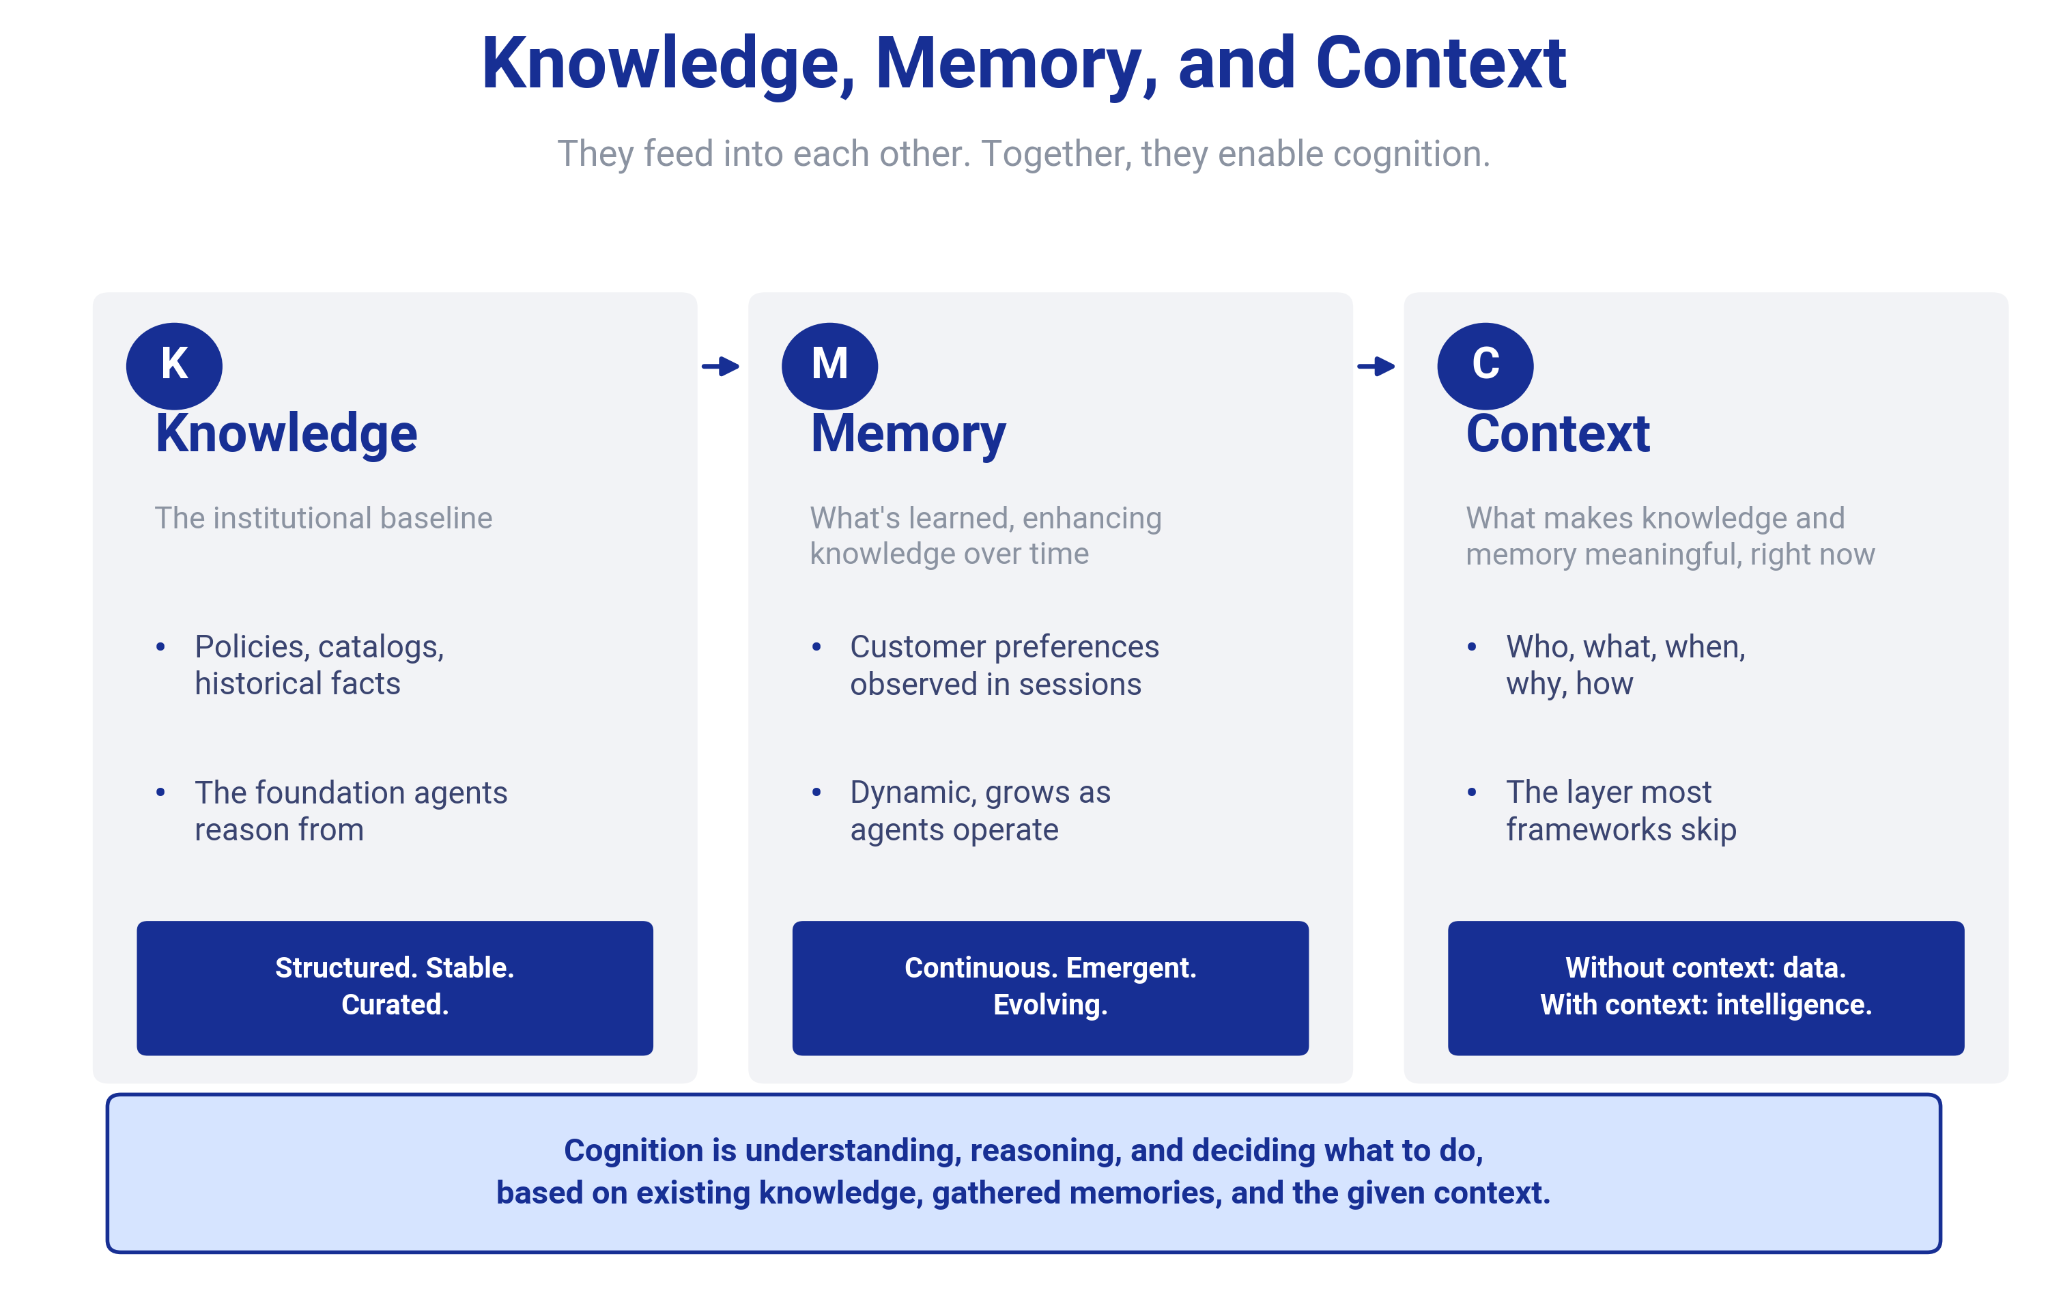
Our own framework for thinking about this, Knowledge, Memory, and Context, started from a simpler question: how do humans actually do this? We wrote about that origin separately in Human Memory As The Perfect Template For AI Memory . Before we built anything, we audited more than 20 memory and cognition frameworks, across memory-first products, agent frameworks with memory as one feature among several, model-native memory tied to a single provider, and specialized research not intended for production. The full framework-by-framework breakdown lives in our three-part series: The Spectrum of Machine Cognition , AI Memory & Cognition Landscape: Deep Dive , and The Architect's Playbook .
Two findings mattered most for what came next. Most frameworks are not attempting to solve for organizational-scale knowledge at all, several say so directly in their own documentation, and almost none treat Context , the who, what, when, why, and how that makes a fact meaningful rather than merely retrievable, as a first-class concern. And "multimodal" usually means an image gets reduced to a caption, or a document to extracted text, with the original discarded once that conversion finishes. A handful of frameworks in our study avoid that lossy step; most do not.
Eight requirements stood out as necessary for this to work at real scale:
- Sessions need to hold more than one kind of participant. A human, an agent, and a customer are often present in the same session, rather than one persona assumed throughout.
- A timestamp alone is not enough. Who, what, when, where, and why all need to travel with a fact, or it will not be usable later.
- Related things need to actually be connected, not merely stored in the same database. Existing knowledge needs a way to be incorporated into this foundation.
- The original data cannot be discarded once it has been processed. It needs to remain part of the record, not be replaced by a summary of itself.
- Permissions must be enforced, not simply recorded as a field that nothing checks.
- The data foundation underneath needs to be fast enough to hold up when thousands of agents are operating across hundreds of thousands of sessions at once, not only in a demonstration with a handful of records.
- Governance is genuinely difficult. The right API and the right hooks can make it achievable rather than an afterthought.
- There needs to be room to add cognition hooks specific to a given domain, rather than a single fixed pipeline for every use case.
As the landscape study concluded: "This landscape reveals a clear divide: while almost every framework can store data, very few have mastered the connective tissue, the seamless synthesis of Knowledge, Memory, and Context required for human-level cognition."
None of these eight requirements are solved by choosing a smarter memory framework alone. They are solved by bringing together the right data foundation, adding the right memory framework on top of it, and exposing that combination through an API that includes the right hooks for cognition, built together with real users, not in isolation.
Getting the Architecture Right
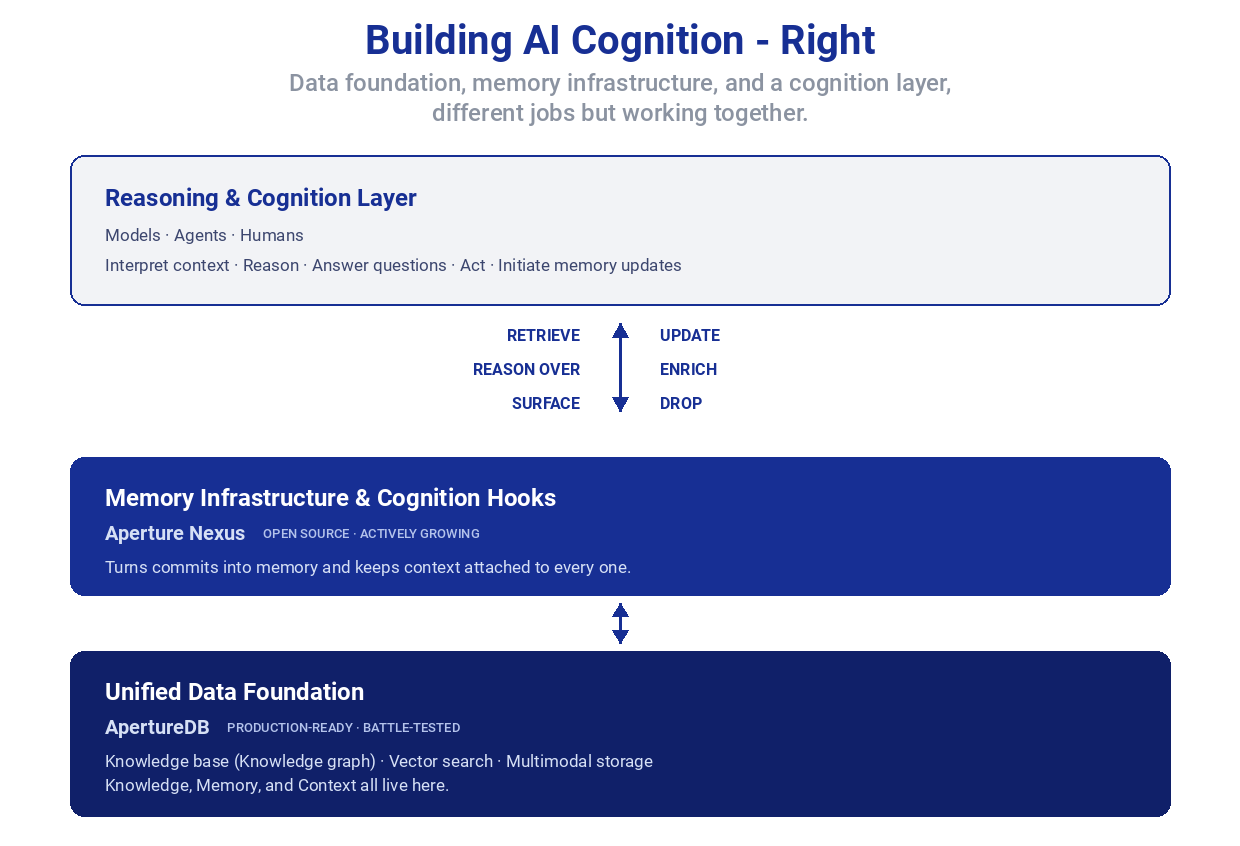
That combination is the architecture: a foundation underneath, and a memory framework on top of it, each doing a different job.
ApertureDB: The Foundation
Without a unified data layer, a typical AI application or agent needs three to seven separate API calls across different components to retrieve the right data for a single decision. One reason is that an agent needs two fundamentally different kinds of memory to reason well. Semantic memory is the general facts and relationships that don't change moment to moment. Episodic memory is the specific trace of what happened in a particular interaction, when, with whom, and why. Most architectures scatter these across separate systems entirely, a vector database for one, a document store or cache for the other, with nothing connecting them. Each additional call across that boundary is an opportunity for latency, for two systems to quietly disagree, or for a query to fail in a way nobody notices until a customer does.
Vector search is not optional in any of this, it is foundational. Embedding-based retrieval is how you find what is semantically similar, and how you surface an episodic memory that is relevant to a new situation even when the wording does not match. But similarity alone does not tell you how an episodic memory connects back to the semantic knowledge it is about, or how two episodes relate to each other. That is a relationship, not a similarity score, and relationships are what a graph represents natively.
My cofounder and I both came from Intel Labs, where we built graph-based multimodal storage for AI workloads. That background informed three decisions we made for ApertureDB, years before Aperture Nexus existed as a name.
Graph as the organizing principle, not a feature. Teams often treat graph structure as something added on top, a way to attach relationships alongside embeddings after the fact. We built the graph in as the spine, with vector and graph search running natively. The entities in a dataset, people, categories, sources, are not metadata fields attached to some other object. They are nodes, and the relationships between them are first-class. A query can traverse those relationships natively, without the application stitching results together afterward.
Everything lives together. Not linked, not federated, but actually together. Multimodal data, images, video, audio, documents, text, embeddings, and metadata, need to live in the same database rather than distributed across separate systems that reference one another. Every system boundary crossed adds latency and creates an opportunity for two systems to fall out of sync. A clip indexed in a vector store whose entity relationship is never updated will return a wrong answer, silently.
Everything is accessed together. An image node carries its pixel data and its embedding together, linked through the graph, including to its metadata and its relationships. You can update or delete everything together. No orphaned vectors need to accumulate quietly in a corner of the system. An episodic memory with a stale embedding is worse than no memory at all, because it can become a confident, silent lie the next retrieval will surface.
The result is what we think of as a persistent, multimodal, shared enterprise knowledge base, memory at scale rather than a per-agent, per-session state. This is also where Knowledge, the K in KMC, lives: semantic memory in the terms above, the stable, institutional baseline, catalogs, policies, and historical facts, built directly into ApertureDB, sourced once and shared, rather than reconstructed in every conversation. Episodic memory, the specific commits Aperture Nexus writes, lives in that same store, connected to the semantic knowledge it draws on.
In terms of performance, scale, and reliability, ApertureDB is already in production at Fortune 50 scale with Home Depot, and Gracenote, a Nielsen company, runs petabyte-scale video semantic search on it today. Aperture Nexus's performance claims, sub-10ms vector search, roughly 15ms graph queries at billion-node scale, are measured on this same engine used in those production deployments.
Aperture Nexus: How Commits Become Memory
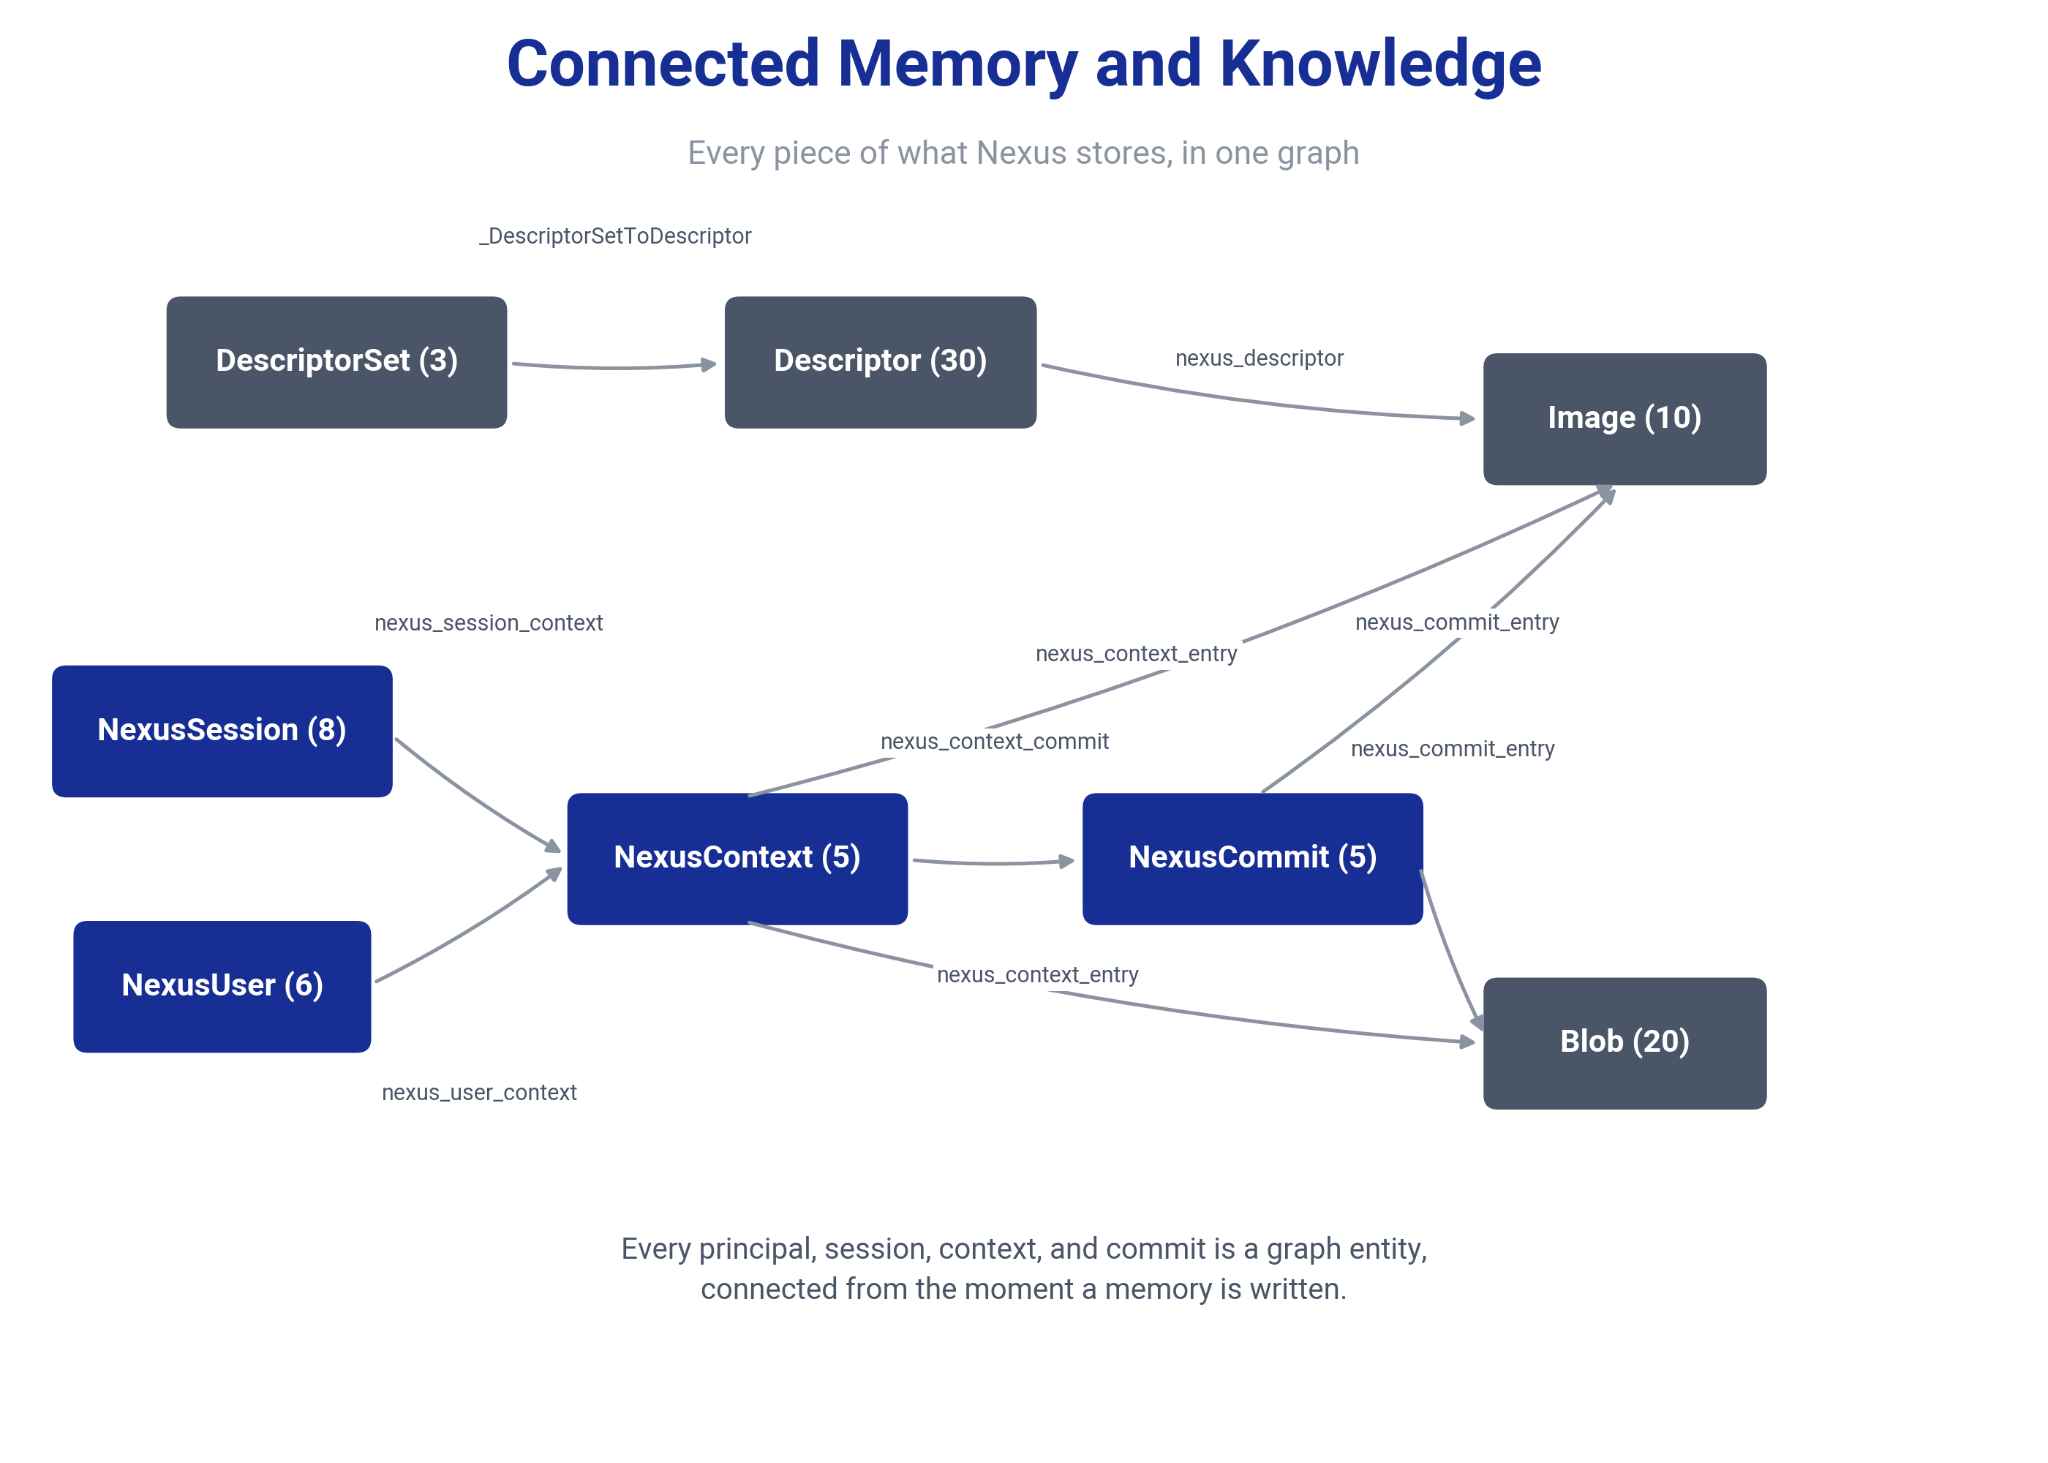
Aperture Nexus ( open source repository ) sits on top of ApertureDB. Information staged in Nexus becomes a memory when Nexus commits it, a durable trace in the database, carrying its own connections to the context that authored it and the commit it was part of. Context (who, what, when, why, and how) is stamped on every commit so retrieval is meaningful, and contexts can be linked to one another with named relationships, follows, caused_by, references, to express how they relate. Knowledge (the loaded baseline, semantic memory) and Memory (accumulated commits, episodic memory) both live in the same ApertureDB store. Cognition is what the whole stack enables, surfacing the right information for the situation and enabling updates to the store when needed. It is open source and still early, growing quickly alongside the users building on it.
The graph model illustrates what this looks like in practice: sessions, users, contexts, and commits, all connected to the descriptors and blobs they touch, in one database rather than scattered across systems that must be queried separately.
Here is an example customer support agent using Nexus with multiple user and AI agents collaborating to surface the right information when needed.
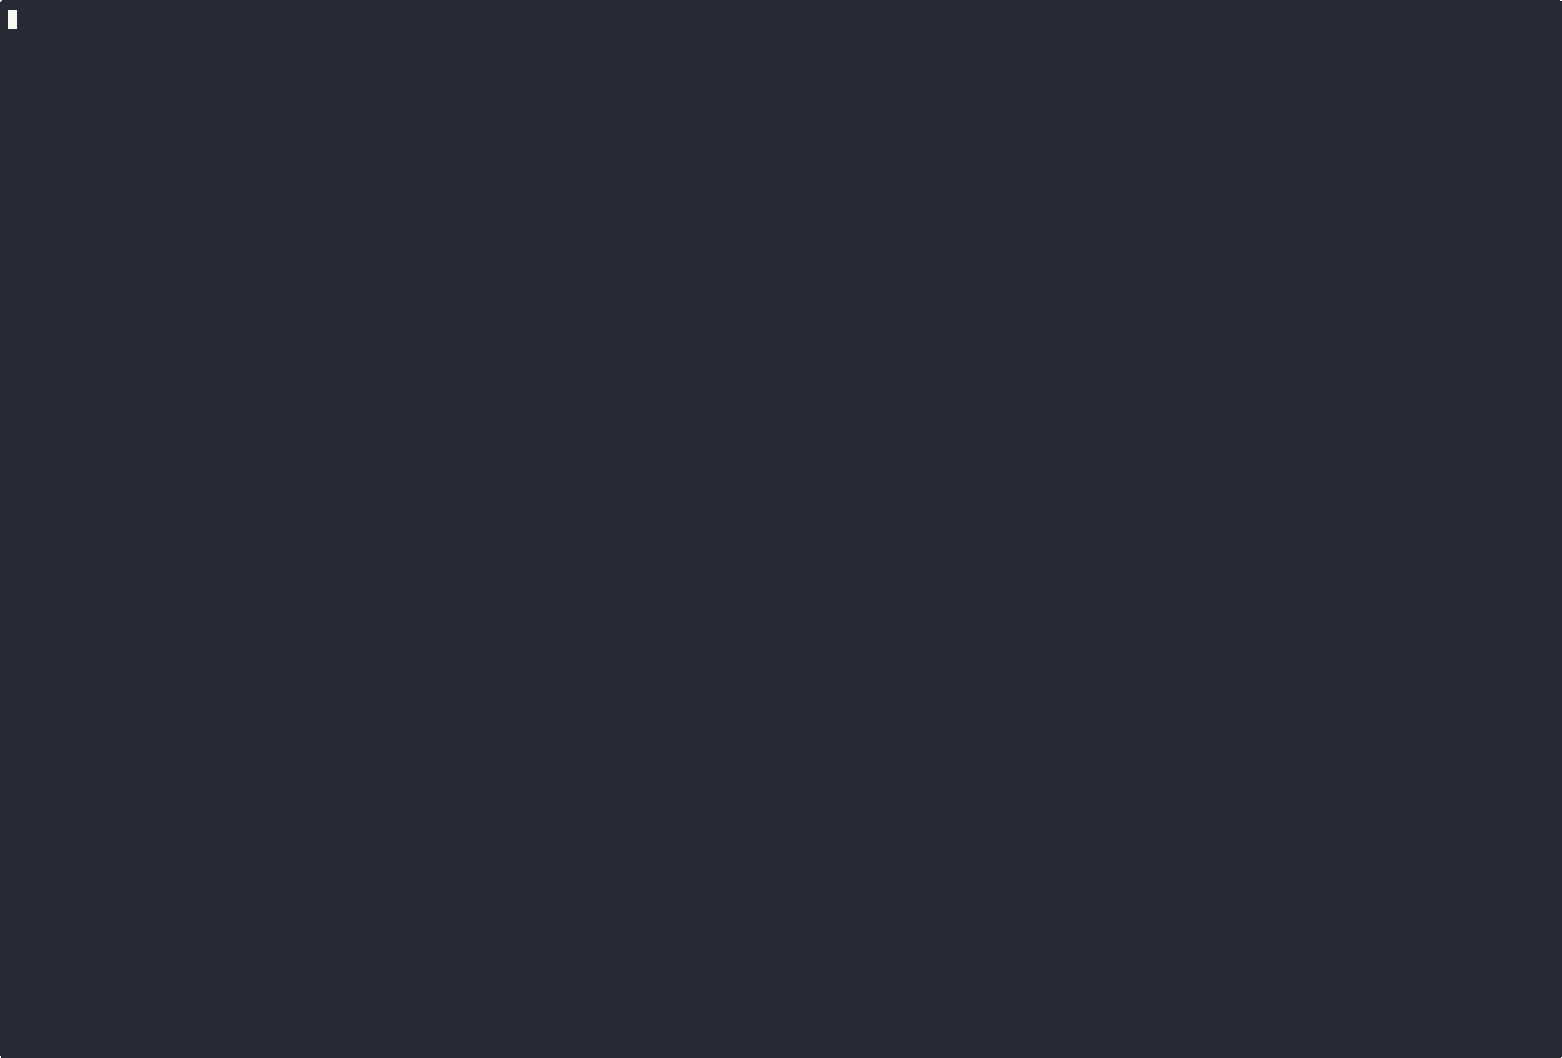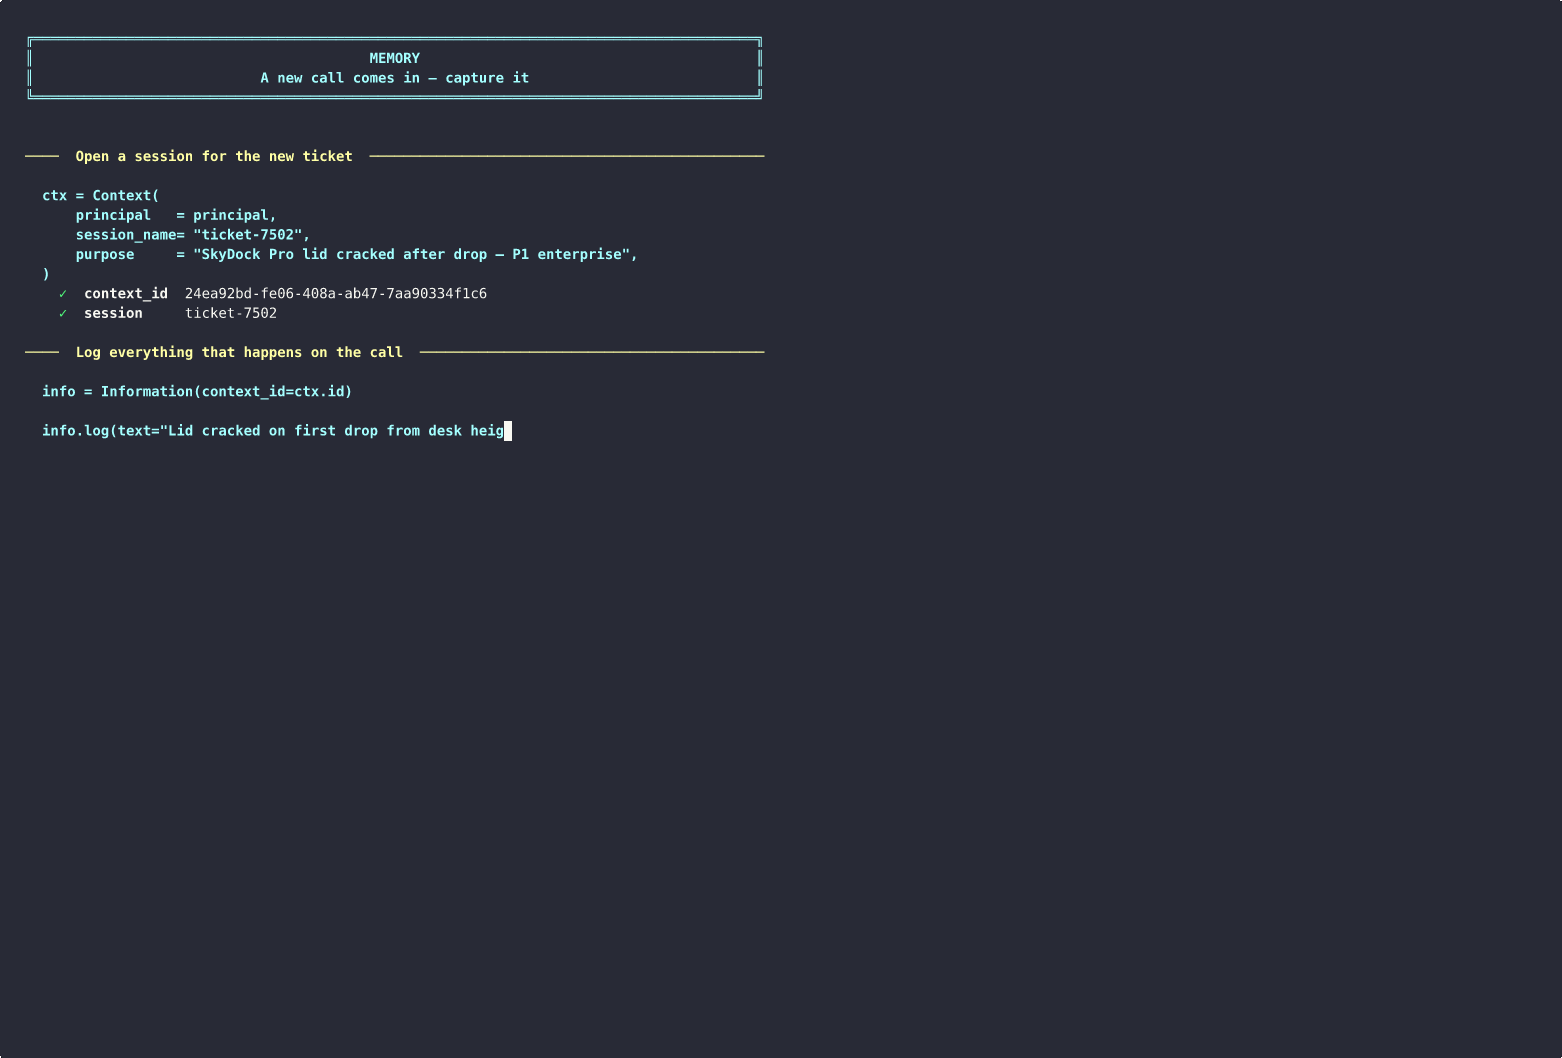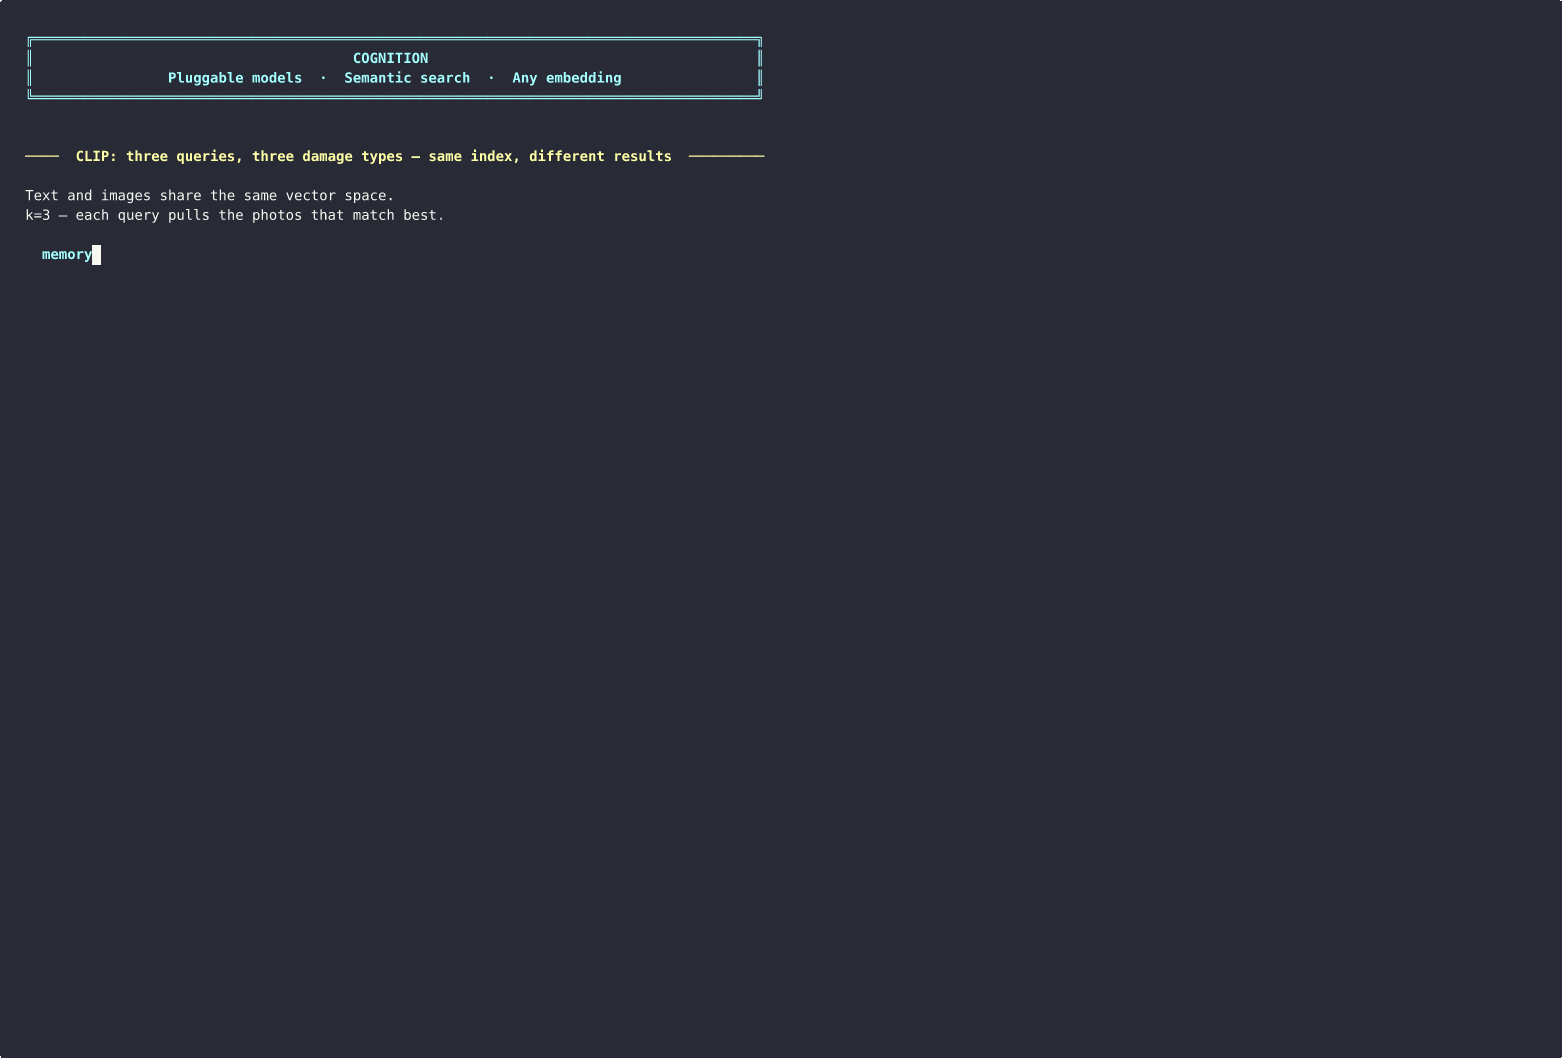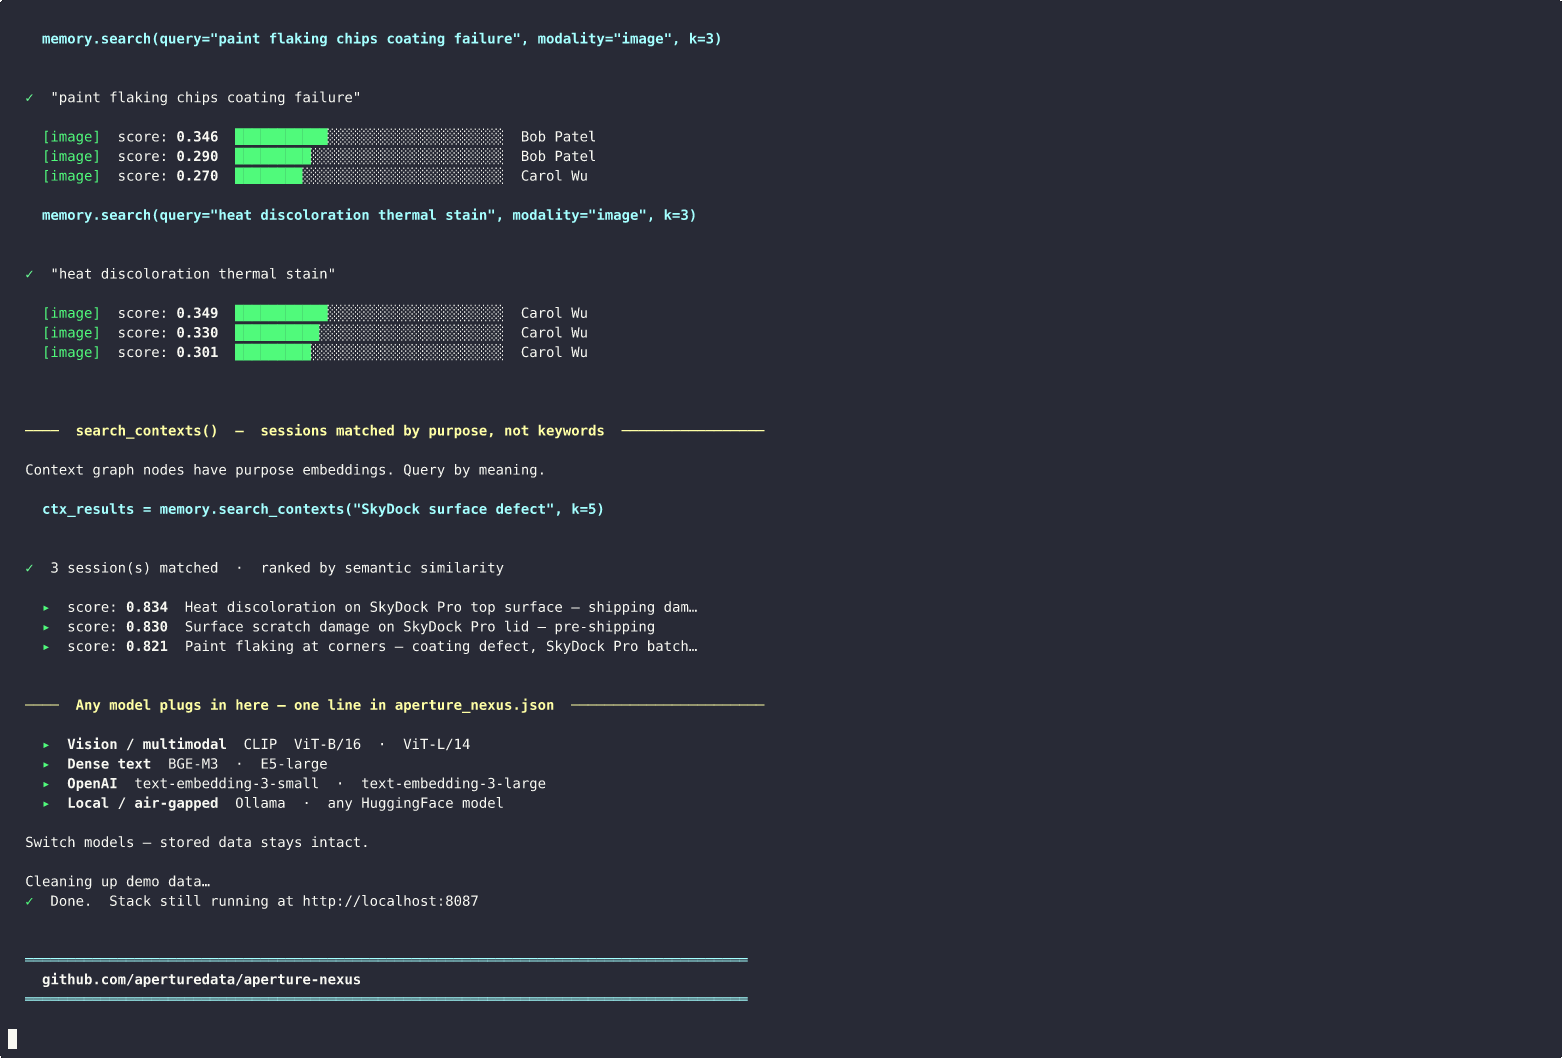
Aperture Nexus in action: example customer support agent demo
The Cognition Gap: What Building With an AI Coding Partner Taught Us
We test-drove early versions of Aperture Nexus the way we want any team to work with it: by actually building against it, not just checking boxes. One example from that process stuck with the whole team. I had an AI coding partner, I call her Claudette, build against a real specification. She delivered clean, well-structured code and told me, with complete confidence, that every unit test passed.
They passed. They simply did not run. The tests were mocked, thoroughly mocked, mocks testing mocks, and each time I asked about integration tests, she found a new way to describe not having written them.
That is the Cognition Gap in one sentence: Claudette had the Knowledge, the specification, and the Context, the session, but not the judgment to recognize that a mocked test is a hallucination wearing a green checkmark. Cognitive science has a name for that judgment: procedural memory, knowing how to act, not just what is true or what happened. ApertureDB and Aperture Nexus hold the other two kinds. Procedural memory lives in the reasoning layer itself, in a model's or a person's own learned behavior, which is exactly why the hooks in the diagram above matter. Retrieve and reason over were not enough. What Claudette needed was surface, a way for either of us to see what she was actually relying on, and update, so the pattern could be corrected once we saw it.
But the hooks themselves are only the mechanism. Whether a mocked test is acceptable at all is a business rule specific to a team, a codebase, a company's own engineering standards, not something generic memory infrastructure can decide on its own. That judgment belongs to a higher, domain-specific layer. The hooks are what let that layer actually see the pattern and correct it. Without them, the judgment has nowhere to attach to, and the same mistake just repeats, confidently, indefinitely.
Trust Does Not Come From Any One Piece
None of this works if it cannot be trusted, and trust here has at least three separate dimensions that all have to hold up together, or "reliable" is only a word on a slide.
Lineage means a decision can be traced back to its actual source, the image, the document, the specific session, rather than a summary of a summary, the same problem that started this piece for us: wanting to know how an image had arrived at its current form.
Permissions are a second dimension. Aperture Nexus already captures who a fact belongs to, at the individual, team, and organization level, as part of every stored object. What is not yet true is that those permissions are enforced at query time, only that the input exists at write time. That gap is one of the reasons visibility enforcement is a v2 priority rather than a nice-to-have.
The third dimension is trusting that the model itself did not hallucinate, a different problem from either lineage or permissions. A perfectly governed, perfectly permissioned fact is only useful if the reasoning built on top of it is sound. This is territory where we expect to collaborate rather than solve entirely on our own. Our landscape study surfaced frameworks built specifically around deterministic decision validation and causal traces, exactly the kind of starting point worth exploring rather than a layer we think we need to reinvent ourselves.
Context on its own is not enough. A fact with no lineage is only an assertion. A permission that exists on paper but is not enforced at the moment it matters is not really a permission. Trust is what results when lineage, permissions, and reasoning are all checked together and that will be a big part of what we focus on with our users.
What Comes Next
Governance
Governance is genuinely difficult, as the eight requirements above make clear, and it is the area we are being most deliberate about rather than rushing. An audit trail that exists by default, not one added after something goes wrong, recording who wrote a memory and under what authority, is the direction we are building toward, with the API and hooks doing the enforcement rather than a policy document nobody reads. The permissions-at-query-time gap described above is part of this same work.
Open Questions in Agent Memory Design
We did not build this roadmap in isolation. At a talk in San Francisco this month, the audience raised exactly the questions we had not fully resolved, and some remain open for us today.
How should the state be represented for something that keeps changing, without either losing its history or accumulating unmanageable versions? Recency and history are not the same query. Sometimes the freshest fact is what matters; sometimes the full trail of how a fact evolved is what matters, and most systems serve only one of those well. When a user corrects themselves mid-conversation, how does that correction reach every other agent already holding the earlier context? We do not believe memory infrastructure can solve that on its own; it likely requires agent-side logic layered on top. And why migrate data into memory at all, rather than holding a live reference and querying in place? This was raised specifically in the context of enterprise permissions: a copied fact does not know when access has been revoked. A live reference would.
None of these are fully solved in Aperture Nexus today and this is where the biggest collaboration opportunities lie ahead.
What's Coming in v2
Version 0.1 of Aperture Nexus ships the core of the KMC model: commit, search, connect, and authenticate, validated against a live ApertureDB instance. The shape of it is simple by design:
What is not yet built: Memory.update() with lineage, so a memory can be superseded while its full history remains intact; visibility enforcement at search time, not only at the moment of writing; GraphRAG neighborhood search; hybrid search combining vector and metadata in a single query; recency-weighted scoring; and an MCP server so Aperture Nexus becomes persistent memory inside Claude Code, Cursor, or any MCP client.
Get Started with Aperture Nexus
Aperture Nexus is open source, under the MIT license. If you have felt the gap this piece opened with, rebuilding yourself for every tool, every session, this is what we built instead. Clone it, run the demonstration, and tell us what would unblock what you are building. We are prioritizing the roadmap based on real use cases rather than assumptions.
With thanks to Sonam Gupta, Sr. Developer Advocate at Telnyx, for her review and feedback on this article.
Dive in
Related
Video
The SAME Project: A Cloud Native Approach to Reproducible Machine Learning
By David Aronchick • Jul 28th, 2021 • Views 313
Video
The SAME Project: A Cloud Native Approach to Reproducible Machine Learning
By David Aronchick • Jul 28th, 2021 • Views 313