(00:00) In SF and New York, they drive around these little three-wheel ticketing cars. I started to do some research and found out they're sold on government auction. In May, a listing came up that I bought and I know you have one. Yes, I took the bit too far to really I have one.
(00:19) I've run loops on my own hardware of like I have a Quinn model running as Hermes that it designs an RL environment, kicks it off, downloads the weights and then hot swaps into this literally Neo learning comes from [laughter] they call it trace to environment and the idea is that you take a bunch of agent traces and synthesize RL environments based on those traces and then train on them and this could work in a continual learning loop like every night.
(00:46) Every task that you've had your agent do while you're sleeping, it goes and creates RL environments, trains itself on them, and updates. We've only trained models to be like this because we expect that they sort of make a wrong mistake and then correct themselves. I actually think they they could [music] reason less and still get to the right, you know, right answer.
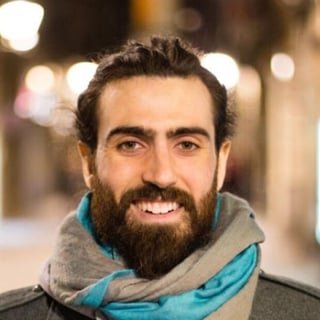
(01:15) We're back and this time I got a old friend with me, Sam, who's working at News Research. You all probably know that company because of Hermes, the agent that has taken the world by storm. Sam's working on RL and it's been great to catch up with him.
(01:40) I just want to like talk through what you're most excited about, some use cases you have for Hermes RL in general, like what you were doing a year ago versus now, how it's changed, and then maybe we can touch on the hottest topic in the world, the continual learning and potential recursive uh what is it? Self-improvement, I think. Recursive self-improvement. Yes, the RSI. Dude, it is so hot right now. So, I laid it all out for you.
(02:03) Where do you want to begin? Uh, thanks for having me here. First of all, super super stoked to be sitting down and chatting. Um, I'll start off with kind of my personal uses of Hermes because that's a good intro to those of the viewers that might not know, you know, what Hermes is or the full power of what you can do with it. Um, and I'll just give a little bit of the context and the background about how Hermes started.
(02:23) And if you know what Hermes is or if you're using Hermes, tell us in the chat because I think that is a good gauge of Oh, yeah. you know, like who's using it, how they're using it. Yeah. Um, so Hermes was started internally as sort of a productivity tool. It was an idea to be like we have open claw and it kind of had had its moment sort of about a year ago and and changed maybe you know nine months ago.
(02:47) was really really starting to to take off and some people internally at Noose were like wanted something different out of it and they wanted to design their own version of kind of a longunning agent harness that would just improve productivity productivity internally like there was no ever semblance of like oh we're going to make this a product and people are going to use it and so we did and they kind of started like telling us like hey you should you should start testing out Hermes and I remember like telling some of my friends like oh yeah we're like testing out this new internally and I didn't talk about it much.
(03:19) Um, I was still using cloud code at the time for all my work. Uh, and I really didn't like have anything that was jumping out at me to use Hermes until one day, uh, I kind of either was bored or I think I was on I was having a conversation with a friend on Twitter, uh, who was posting all these pictures of like ancient art pieces, like these old ceramic pieces and like Native American art, and they were saying like, "How do I find clothes that match this art?" Nice.
(03:49) And that was the first idea clicked in my head of like, you know what, I could probably test Hermes with doing this and just see how far it could I knew the pipeline in my head of like pull a bunch of images from men's clothing site, you know, do some sort of image embedding similarity to the target image of whatever art you're looking for and then rank them by like price or by, you know, whatever. There's there's a million ways to filter it once you have this like similarity distance. So tasked Hermes with doing it and an hour later I
(04:14) came back to him with a a program that you know it was like code was on GitHub in an hour and it could find any clothes currently listed that matched either clothing that you could send it or a picture of something random like you know yeah so I still use that a random item just like pottery that is and it's like what what vibes with this I really am inspired by this pottery I need that. Yeah. All right. I'm going to go look up that. Uh yeah, yeah, yeah, I do. It's it's a um it was a fun use and I still use it when
(04:44) I want to find clothes. It's great. Uh the other thing is in SF and New York, I guess other cities, they drive around these little three-wheel ticketing cars. They're these tiny triangular cars. Yeah. Uh I have seen one in my neighborhood, one or two, and I started to do some research and found out they're sold on government auction.
(05:04) So, in February, the first live demo of Hermes agent that we did on Discord, I got on and showed everyone the end to end process of me tasking Hermes to write a script to search government auction sites every day and find one of these cars. In May, a listing came up that I bought and I know you have one a bit too far to really I have one and I drive it around San Francisco all the time.
(05:28) People probably are like, "No, don't wait. I'm coming back. Heck, I paid for my parking. Well, it's spray painted. It's interesting. It's all It's painted. So, like it's got all this like graffiti on it and stuff cuz the guy who had had it previously was an artist, so it's like people think, "Oh, I'm a ticket person." And then they realize it's like not.
(05:48) Um I'd love to repaint it. It's kind of blue and and black right now. Like it almost is like Hermes colors. Yeah. Um, it'd be cool to have some some yellow streaks in there or like I jokingly calling it the Hermes mobile to co-workers. I mean, it got you the car. It did. It did.
(06:10) And that's one I tell people often like if you're looking for an apartment that fits some specifications or you're looking for a car and like instead of checking Craigslist every day, you know, that's a great use of Hermes is like life admin tasks that like would require you to kind of be on your computer a lot or like be and follow up. Yeah. And you know outside of that we have seen wild uses of hier. Tell me about this. That's what I want to know. There's a lot of people use it for creative um creative pipelines like our launch videos on Twitter. Mhm.
(06:34) Super hype. They're beautiful. The music behind them people love. All done through Hermes through this Hermes workflow that some of our designers have laid out that you basically end to end get this beautiful asy art launch video where it composes the music itself and the whole thing is just this cohesive creative pipeline and so our designers use a lot for that.
(06:57) We've seen a lot of uses of people using Hermes for smart home automation. M so like having Hermes do analytics or control on like your lights or like one person they had like a a dog door that was attached to their smart home and like they could pull the numbers of how many times their dog had been in and out you know within a week and like start tracking the behavior that way and that has a beautiful data visualization.
(07:20) Yeah. Yeah. Yeah. It makes this pretty Yeah. I mean anything's possible man. Like of course a lot of people use Hermes for things like you know automated crypto trading workflows and and market analytics you know I think like we created an internal and sort of external benchmark to evaluate model performance inside of Hermes and there's already a ton of coding agentic benchmarks like there everything out there targets like the majority of what people use that for which kind of comes down to writing and executing code but we wanted to target the things that were outside of that. So, a lot of it was life admin stuff, a lot of it was, you
(07:57) know, managing your utility bills, having Hermes go through your email, compile all your utility bills, and like even draft a, you know, check to send like you you're the last step in the approval workflow for that. And that's what I that's probably what I love is how far it can get without me. Oh, yeah.
(08:16) And because you don't necessarily need to and also you don't need to sit there and explain it step by step. It's like, hey, here's this outcome that I'm looking for. You go figure it out. Once it's figured it out, then you can optimize on it and you can decide like, okay, now that I have this workflow, let's codify it and let's make it a little bit more deterministic where we can.
(08:40) You don't need the biggest model to go and do this every time that we have it because we've already explored the space. We found what the optimal way of doing it is and now we can optimize. And that's the cool part about Hermes, too. I mean, you're teeing me up right there. Is like when we designed it, we started to add in the ability for it to write its own skills.
(09:00) And normally with the aenic workflow stuff, as you were starting to do more, you would tell your agent like, "Oh, write this as a skill." Hermes is just like if you have it do something, especially multiple times, it's all converging to the same skill. I think that was a big unlock, man. That was the thing that made like that magical experience where you're like, "Oh, wow.
(09:19) It just does it." and it it does it like automatically. I don't need to think about it. I don't need to tell it to do it and it knows how to do it. Yeah, it's it's pretty wild. Um, so yeah, we've had a lot of fun and growth with Harmonies and I think this whole landscape is a lot of learning about, you know, what the right paradigms are to to use and how to we talk a lot in news about, you know, time to magic.
(09:43) We want to understand like from someone's first uses of Hermes, how long does it take them to really click and understand that this you know this agent grows with you and has a t like me as that user I how long to like can offload a task and like trust that wow that can get done and I don't have to think about it.
(10:04) Should we talk RL? Yeah. Yeah. This is perfect segue into the rest of what I wanted to talk about. So you asked what I was doing a year ago and how the landscape has changed. Um a year ago I was working on we had our own internal RL framework. I mean it was public.
(10:26) It was open source but like we used it for all of our RL training internally and Thinking Machines had just released their Tinker library which was basically cloud RL. You could offload your training loops to their compute and you could pay them per use. But for a while in their dev, you know, beta phase, it was free. So we basically were getting like this super great deal on like running RL experiments. Um, take advantage of it while you can.
(10:45) That only after a while started to cost us a little money, but still worth it. Um, and I I had was an intern at news for about a year and then I joined full-time in October of last year. So I just passed your anniversary there. Congrats. Thanks. Um, so my first project was to integrate our RL training library into their online RL, you know, their their cloud RL thing.
(11:07) So I built out this whole library. Um, it was a lot of the RL stuff that we do now is very different than what it was back then because the whole idea of like aic RL like was just starting to form. Like a lot of times we were like the stuff I was proof proofing out for this was like ringing on like certain benchmarks like math benchmarks and like different types of problems.
(11:42) Like it wasn't until about March when I was using this framework to build out um it was a project called endless terminals and it was basically procedurally generated terminal use tasks. Nice that you could just keep generating them with varying levels of difficulty and then training the model on it and it would just get better and better at like this complex terminal management. Talk about Hill Cloud. I know which is like ground zero for agent performance. you you optimize that your agent gets so much better out of the box. Um, so that was a really cool one.
(12:06) And what I'll say about this is that the main contribution I made to Hermes, which we ended up moving off of our RL framework, but in the early days, this was the biggest pieces of code that I ported into Hermes agent. We built that idea of using our RL framework with this on, you know, this cloud compute into the earliest version of Hermes.
(12:30) And the idea being that if you're running Hermes with a local model and you h have an ability within Hermes to design an RL environment, kick it off on some cloud compute and just let it and then download those weights and replace them with whatever is running in Hermes. It's like hot swap. Yes. You never Oh, it can teach itself a skill. Like if you task Hermes with like I want you to create an RL environment to learn how to use the terminal better.
(12:56) Yeah. Right. or I'm having a horrible time with this ERP system. Yeah. Like here's a bunch of data of me using it. Go make it easier for you to use it now. Yeah. And so that was the earliest like embers of what we would see RSI becoming. And there's there's a lot of other ways that this has all kind of come into the fold.
(13:23) Um, but that was a big contribution I made and I felt, you know, I I've run loops on my own hardware of like I have a Quen model running as Hermes that it designs an RL environment, kicks it off, downloads the weights, and then hot swaps into this literally Neo learning kung fu. [laughter] I know kung fu in the moment and you're there like, "Oh, sweet. My model is now much better." Yeah. And it can do that. But then it changed.
(13:50) Yeah. So we ended up like our our training framework was good but a lot of priorities in the company have shifted since we did all that. Namely Hermes agent took off way more than any of us expected. So we shifted a lot of resources towards that. Um model training paradigms got a lot harder since then.
(14:15) like the the deepseek RL explosion was sometime, you know, like it it was recently enough that people are just now figuring out how to really harness like not only RL on specific tasks or specific task types, but this like long context, long horizon RL and like really hammering it for aic loops and like aic, you know, models. And I think we've noticed this a lot in like the latest, you know, anthropic series of models.
(14:41) Um, I think all of the openweight Chinese models that have come out have since, you know, really benefited from focusing on this like longer context stuff. Um, the first one that I I'm I'm I'm forever will show this model because I personally love it. Um, so Xiaomi, the the telecommunications company and car maker. Yes. And car maker, right? Yeah. The the massive incredible car maker.
(15:05) I'm I'm really thinking about getting one cuz I live in Germany and they can ship them over there. Yeah. Yeah, you should. I know. See them a lot. They seem really good. Anyway, I digress. What do they do? They were some of the earliest to jump on um this stuff and they had also picked up focusing on on training specifically for Hermes agent pretty early on and they're doing it in the open like writing papers about it or Yeah. Yeah. Really? And so I haven't seen this at all.
(15:32) Xiaomi is like I was a fan of their model. It performs really well in Hermes for its like weight class or whatnot. Um and so you know we were really inspired with what they did to sort of we've been we've been amassing all of these different learnings and basically saying like okay if we can take you know all of this aenic open training and stuff and and we're just kind of reshaping the post-training team to be able to do this kind of thing well. Like that's I think our goal as the RL post training team at news is we got our start training models
(16:03) and we have a really strong talent density in terms of the you know there's eight of us and we can train a a really good model given the right so time and resources that is so wild. So we've been sort of biting our time and making sure we can do it right. Um and so definitely more to come on that soon. How does it go to the continual learning like explain that now where you're at with all of it? I'm glad you asked. I'm glad you asked.
(16:29) So, Xiaomi, the latest model is Mimo V2.6 Pro. In that paper, they talk about this brilliant thing that has come out lately and is sort of obvious when you think more about it, but still the idea struck me um they call it trace to environment. And the idea is that you take a bunch of agent traces and synthesize RL environments based on those traces and then train on them. And this could work in a continual learning loop like every night, every task that you've had your agent do while you're sleeping, it
(17:00) goes and creates RL environments, trains itself on them and updates. Um, or you could do, you know, amassing tens of thousands of different traces on data sources that you have like spin up a bunch. Yeah. Yeah. If you have a lot of data of Hermes agent uses, what we do first is what's called failure analysis.
(17:20) So, we go through and find the exact points where the agent makes a mistake. Then we cluster those by the mistake type. And once you have a bunch of different piles of, oh, the agent, you know, entered the wrong directory here or, oh, the agent, you know, copied the wrong file here. Like you just have a bunch of different types.
(17:42) Then you can sort of build an environment that captures those mistakes or build a bunch of are you human labeling those or is that all all automated pipeline? Also awesome. Yes. And so again, that helps with the recursiveness of the Yeah, huge. Okay, that was one of the last things I've built at news was like our internal it's we call it the insights and observations pipeline.
(18:04) It's actually based on some research anthropic publish where they do the same thing and they didn't publish the code for it obviously but they did publish their methodology. So we sort of co-opted that between claude itself and their claude code variant of doing it and built our own internal pipeline that does this insights and observations like failure analysis clustering and then we have someone working on lately which I'm going to start collaborating on too um you know environment synthesis and then we can just loop that.
(18:28) What's the environment synthesis? it. That's the generation of like you you take a bunch of failed traces and and you have a bunch of examples of like here's where the model messed up and then you build some kind of like fake environment that that's supposed to match pretty closely to like those like the world that those environments were in like the state of that computer at the time and the files but it's not the real thing obviously.
(18:54) Um it's just synthetic and then you can add sort of levels of difficulty based on how well models do. How often are you trying to train on like gigantic cloud or so not train on the cloud but like train for cloud environments because if I've got a bunch of different AWS services I'm using and maybe I've got some Google Cloud services I'm using and I want to recreate a little bit of that.
(19:23) Can you bring that into the environment? Yeah. Yeah. We've done a fair bit of like Google Cloud, you know, simulated like cloud environment training too. And and I think that that's a lot of this is very green. Like there's so many areas of exploring ways in which you can put an agent in the simulated scenario that we like probably haven't touched yet.
(19:47) And I think exploring like cloud deployments and and managing cloud infrastructure is one of them because a lot of times the traces that we see or the traces that we get from ourselves are all Hermes running on our own local hardware or local machines. That's what I was thinking.
(20:04) But if you're oh maybe you want to start serving a bunch of traffic and you want those traces too and you want to see like oh that now the agent is trying to fix something on production traffic or simulated production traffic, right? but it's messing up and we've got a se one incident and then we can see that cool it's messing up here. Let's spin up that environment, kick off another training run and have that whole loop happen again. Yeah. So, I'm very excited about that.
(20:24) That is one of the most the things I'm the most excited about and I think is a very healthy place that the RSI conversation has turned to. uh is less of like just having the agent decide like to teach itself some new skill because we kind of do this already with like the tears of memory in Hermes and this like automated skill writing like the agent can kind of already bolt on things that it's learned to itself in context but learning from its own failures you can only do so much without sort of this this idea of like like just
(20:58) collecting all the failures and building some learning environment for it And yeah, you know, that might honestly be what's left in post training. Like everything else has kind of been really Yeah. I mean, there's a lot there's a lot to do, but I think that that's like the last like Yeah.
(21:20) I I mean only thing we can do right now is improve models for agenic use cuz that is by far in a way like what we care about models doing. How long they can act in a harness, how long they can go without making mistakes. Yeah. improving token efficiency is one like that's one I explored early on in my research I was like you want a model to be able to finish a task as efficiently as possible and then there's this like exploration versus exploitation balance of like you want yeah you want it to spend some tokens exploring other options but if it knows that it's going down a wrong path you don't want to waste a lot of turns or tokens doing that
(21:53) yeah you know what messes you up there though is like the models will a lot of times times lean on their pre-training. Yeah. And so you say like you want something done and it goes, "Oh yeah, I know how Versell works." Meanwhile, Verscell came out with a new version and guess what? You don't know how Versel works. So it doesn't go and like read documentation or try and figure out how it works because it says I know how it works.
(22:17) And then later you're like, "Ah, it doesn't work like that, does it?" You get these I don't know how to explain it but there's those moments where you the mod the model is magical because it knows things but it also is almost like it's Achilles heel. Yeah 100% that and that used to happen a lot worse. Yeah, with knowledge cut off dates and now less so, but I think a lot of labs are trying to train models to act with the oh, I should look this up instead of, you know, oh, let me pull from my uh from my memory. But but but then it's not as token efficient, right?
(22:53) Exactly. Because then it has to read through the documentation. Yeah. So, that's what that's what I was thinking like if you're doing research on token efficiency like you want that but you don't uh it's about it's a huge trade-off and for me token efficiency comes more in like long reasoning traces like I think there's a lot of cases in which models sort of overreason because they've been sort of trained into this basin where like this longer reasoning answer involves a lot of backtracking and second guessing.
(23:22) I think a lot of that is I mean this is like my personal hot take is I think that like a lot of that is somewhat unnecessary and that like we've only trained models to be like this because we expect that they sort of make a wrong mistake and then correct themselves and like most of these models are good enough like I actually think they they could reason less and still get to the right you know right answer.
(23:42) Yeah. We also just kind of assume that the longer it reasons, the more correct the answer will be or the more accuracy we're going to have. Yeah. At the end of the day and that's true that potentially like a lot of that reasoning is wasted reasoning. Yeah. It's just tokens like and you know on the contrary like I did do research on this.
(24:07) I published a research uh blog about this. It did turn out that the longer you have a model reason, the better it does in in generally constrained setting. The intuition is right. But but I also think that like a lot of people liken this to a turning tape analogy. Like if you're computing a program on a touring tape, like the longer the touring tape, the more you know you're going to approximate the program you're trying to compute on it. Like this classical old computer science analogy.
(24:32) And that's roughly the case here. Um, I wonder if there's a point of diminishing returns. Like I was looking at, you know, up to maybe 2,000 reasoning tokens, but like when you're reasoning for 10,000 tokens or more, like there might be a a diminishing returns point. And yeah, I think it's worth looking into more.
(24:49) Um, but that's also one that comes into training. Like a lot of training regimens these days involve like reasoning length or, you know, token efficiency and reasoning. Like sometimes you want the model to reason less. It's usually there's less room for mistakes.
(25:09) The newest Quen series has three reasoning settings and default is extra high, but you could do, you know, medium and low reasoning if there's some cases where you might want that. Dude, I'll tell you what, I never know how to for whatever task I'm giving. It's always high and then every once in a while it's like, ah, I think this is this could be medium or low. We'll see. Well, first of all, like the I'm pretty sure the OpenAI models, they don't even have low. No, it starts at medium.
(25:32) Yeah. Yeah. Yeah, they so like and then it just goes medium, high, extra high, ultra high like I don't understand when I should be using these. I have no idea. It's so complicated. And please can it just figure it out for me? Yeah. Like that is the fact that we have to decide what we want is a little bit for me it's probably like an artifact of today. Yeah.
(25:58) But I get the feeling it's not going to No. I also I mean I never think about it and I don't change the options. I'm like I'm always using the highest reasoning because I just don't think about it. That's it. But then you end up wasting a lot. Yeah.
(26:17) It's I I think it that's just like a a hypothesis that I'll put out there is that that's likely the case is that there's maybe more of a dynamic way you could control reasoning length. Um and then you would also ask like things I'm excited about. And right now the areas that I'm most excited about with all of this actually are even outside of the RL post training regime um inference time improvements. You know, I think between there's there's a lot of work that comes out in steering and like using these external vectors and activation math to like guide a model in some behavioral direction. Yeah.
(26:49) And then also sampling like the order you pick the tokens. My earliest research for the token efficiency thing was in sampling and latest research that I've published um was in steering and it was specifically focused on like refusal steering like safety related work but I am more interested in steering towards behaviors that could make an agenic model better especially smaller models.
(27:12) Yes. So like an example is like if you're solving a math problem, if you had some way to steer the model towards being more pragmatic, like if you could multiply some of the activations in it at inference time and be like, "Hey, you're solving a math problem. I want you to like go hard." Yeah. Be more pragmatic. Or if it's doing creative writing, I want you to do more at inference time. Yeah.
(27:34) It's almost like you have latent Lauras or something. It's in essence, it's kind of the same thing. you it's like a trained adapter that you can basically choose to add in at inference time and luras are an extension or sort of a parallel you know adjacent thing to that that you can train specific loras and hot swap them and Apple was one of the first people to publish research.
(27:56) Yeah I remember that's why it was like oh yeah I think somebody was doing that and you can have that come in and especially when it's on device it's very useful. Yeah. Super. But then you're talking about it a little bit different and you're saying not necessarily these luras that are hot swapping in.
(28:12) It's just inside of the actual uh transformer. It's like at the it's it's at the end like the mechanism that would be multiplying the vectors in is external to the transformer, but there's no really swapping. It's it's sort of just multiplying a vector into the the last layer of the model or whatever as it's sampling to change the behavior.
(28:35) And you would create that when you're rling the model. I would we would create that as sort of like an external thing that builds into the inference engine. So that's like my vision is that if we are able to serve inference so into like VLM. Yeah.
(28:56) into like a VLM, you know, side car that basically does this like dynamic and and that I think is like a really underexplored area of improving small models cuz right now we're kind of trying to RL them to death to get performance gains or distill the out of them, make them super small so you can have them on edge and then you're it's a different story when you're saying you can still get the value of the small model or of a larger model but with that smaller model maybe you need it on Yeah. And I think I don't know.
(29:22) I I just think again there's some areas of this that are really underexplored. Uh and so this is one I'm personally very excited about. I think most people don't want to touch it. Uh it ties a lot into like the interpretability field and understanding. Oh, really? Yeah.
(29:40) Because if you can control a model's behavior, likely you're getting closer to understanding the components that you're touching where those behavioral things come from. It works a little bit in the other way where if you do understand a behavior then you can easily control it. And sometimes when we do the steering we control something and think that we can explain backwards why it actually you know exists in the model.
(29:58) Normally not the case. Um, but that's why they're like the this ven diagram overlap of like understanding the model interpretability steering like controlling behavior and like the middle is is when you hit both on the head and and you understand both the components that exists and how to you know maneuver them.
(30:21) I'm normally focused on the latter like I only care kind of about steering behavior. um at least in this agenic context like I'd love to understand how a model works but for us it would be really beneficial to be able to just kind of guide it in these ways um yeah because you can get such a better outcome and it's just two sides of the coin it's like one you're training this behavior into it and sort of designing these RL environments and these post-training environments to like converge into the behavioral basin that you want and the other you're sort of sprinkling it in at inference time and and choosing to like like, you know, and
(30:53) I I just have a hunchology. Yeah. I have a hunch that there's these ways that you can you can sort of do it a little bit more um deliberately and and a little bit, you know, more fine grain at inference time. In my head, I almost envision that animation that you see when you look inside of how a key clicks all of the different pieces of a lock before you can open it.
(31:22) It's like you need certain things to be lit up. And so then you get that key and it sticks in and then boom, we now have this model. It's the same model, but because we put the key in it this way, it hits all of these different pieces and then you can open it and it gives you that. Yeah. Yeah. And and every lock is a different, you know, you insert the key for one behavior and all of a sudden now you've Yeah, that's a great analogy.
(31:44) I think this or or like swapping, you know, how like gears kind of sometimes So you have like oh the gears fold together like this that kind of thing. I'm I'm seeing it very visually because it is so it is pretty uh abstract in a way. So I'm like only visualizing it and it's it's a little bit harder to figure out the um the things on it.
(32:07) But dude, okay, so last thing I wanted to mention on this was well I mean there's so there's so much and I just got word that we got one minute left. Um, so I'm going to try and like close it up, but you kind of blew my mind on a few of these pieces. So that damn I I as I went into the visual analogy, I start just thinking about all different kinds.
(32:30) But uh what I wanted to say was my friend Linus. One of my favorite talks that I've ever seen was from Linus Lee three years ago when LM first came out and he was doing a bunch of interpretability stuff and he was talking about how we can visualize the inner workings of how the model is coming to its conclusion and hopefully we can get different ways of interacting with it.
(33:02) So he in this talk he talked about how when we interact with computers sometimes we will use histograms or sometimes when you're like with music you can have a high pass or a low pass and you see the ways that you're interacting with the um the generation or the computer generation in a different way than just like oh we're looking at output like just a bunch of text log dogs and whatever.
(33:28) And it feels to me like some of this stuff that you're talking about, it would be so cool to see a histogram of the inner workings of how it's going. And can we steer it differently? Not necessarily steering it in how we want to like type and say it needs to go this way or that way, but can we like have this RSI loop training and we are deciding how we want to steer things because of a histogram.
(33:53) I know it's way out there and I may have no I mean you're touching on like all of this does connect if you can understand components of it and the visualizing as a whole like everyone's trying to figure out the best way to visualize this kind of stuff but if you can understand different components of a model and sort of you know shuttle RSI learning updates into them like eventually we will get to what we envision as like true continual learning like a model that can just update itself constantly like we humans learn like that's the goal is we want to be able to understand like how to update
(34:25) one track in the model's mind and not do a full wave update of like every little neuron gets changed and we don't know why. Like we want to know why and like if I encode some factual information about Agent Con in San Jose 2026 like I want the one pathway in the models, you know, neurons to encode that information. Um so I think you're that talk sounds interesting. You should I'll send it to you. All right.
(34:49) So, we're going to shoot over to the next talk, speaking of which. And let us know in the chat. I'm going to go look at it now what you think. If you're using Hermes, uh, give a shout out to Sam. Thank you for doing this, dude. This was awesome, man. And I'm like, I'm really glad we got to nerd out on it. Yeah, me too. This is great.
(35:08) We'll see you all after this next talk.